 ·
8 minute read
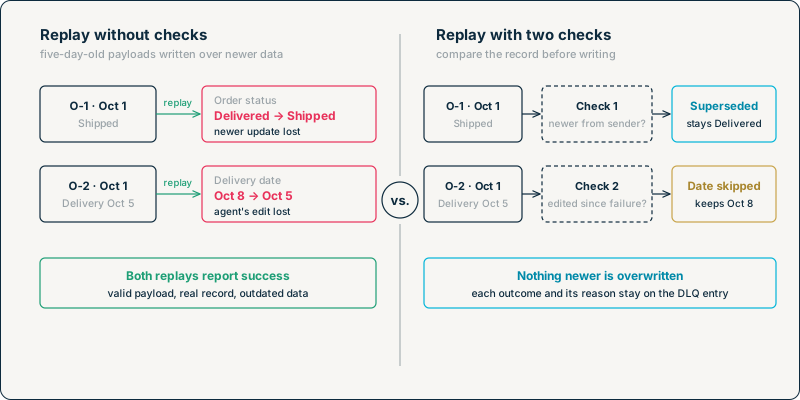
On October 1, Airtable had a brief outage while an order system was sending updates. Two of them, for orders O-1 and O-2, run out of retries and go to the dead letter queue, each one setting the order to Shipped with a delivery date of October 5. The order system keeps working after that. On October 3, a customer service agent moves O-2's delivery date to October 8 after a call with the customer, and on October 4 the order system sends a newer update for O-1, Delivered, which goes through. On October 6, someone in Data Ops works through the queue and presses Replay on both.
Both replays find the right orders and report success. O-1 goes back from Delivered to Shipped, and O-2’s delivery date goes back to October 5, overwriting the agent’s change.
InAir’s guide to operating Airtable inside complex, high-volume system landscapes makes replay idempotent under Principle 3, which stops a replayed create from producing a duplicate record. These replays were updates, and the overwrite gets through because each payload is valid and matches a genuine, live record, so nothing in the write itself shows that the data it carries is five days old.
This post covers what to store so a replay can tell, how the replay decides what to write, what happens to a payload that's out of date, and how to handle a second press, a batch of related failures, and the audit trail.
The Warning Without a Mechanism
InAir's guide to Architecting for the Failure State already names the risk. Its Retry button comes with a caveat: "This action is only safe if the record has not been modified downstream by other systems or operators." It asks the operator to check before retrying, and that's where the check stays, in someone's judgment. The re-evaluation button in Preventing Silent Failure Chains sends a record back through validation, which confirms the payload is well-formed but not that it's still current.
The replay has to answer that question itself, before it writes anything: has the record changed since this payload was produced? The two orders above show the two ways it can have changed, and each needs its own check.
Two Checks, Two Clocks
A newer change from the same sender. O-1's October 4 update is newer than the October 1 payload, and both carry the order system's own timestamps. This is the comparison Out-of-Order Updates sets up for live writes: each Airtable record stores the sender's timestamp for the last write applied to it, here in a Source Updated At field, and an incoming write older than that value is rejected. A replay is a write that arrives very late, so it goes through the same comparison. If the record's Source Updated At is the same as or later than the payload's, the sender has already delivered something at least as recent, and the payload is superseded.
Store them in Airtable date fields with the time included, and have the integration send them as ISO 8601 timestamps, the format Airtable’s API uses for date fields. The display format chosen on the field only changes how the date looks, not the value that gets compared.
If the live integration already uses 3.2.1's timestamp comparison, it already maintains Source Updated At, and the replay only has to read it. If the sender can produce two changes with the same timestamp, the same post's case for version numbers applies here too.
A change from anything else. The agent's edit to O-2 didn't come from the order system, so it never touched Source Updated At, and the first check can't see it.
For fields that more than one writer can change, use Airtable’s Last modified time field. A single Last modified time field can watch several fields, but it only tells you that one of them changed, so for a check that runs without a person, give each shared field its own Last modified time field scoped to that field alone.
3.2.1 notes that this field records when Airtable applied a write, not when the change happened at the source, which is why it doesn't work for ordering live writes. It's the right tool for this second check, though: whether a field has changed since a given moment. The moment to compare against is when the failed write was first attempted, so the integration records that on the dead letter queue entry as First Attempt At.
That comparison crosses two clocks: Airtable's, which sets the Last modified time, and the integration's, which sets First Attempt At.
Subtract a margin of a few seconds, ten in the script below, to cover delivery delays and clock drift, and treat any change inside it as newer than the failed write. A margin that’s too wide only means an entry goes to review when it could have been replayed.
The second check only exists because those fields have more than one writer. In Integration Load terms, ownership is one of the two containment factors, and it shows up directly here. A field only the sender writes needs the first check alone, while a field the sender and the support team both write needs both, and a reviewer for whatever the second one skips.
What the Replay Does With the Answer
|
Result of the checks |
Replay Outcome |
Status |
|---|---|---|
|
Neither check finds a newer change |
Replayed: every field is written |
Resolved |
|
The sender's timestamp on the record is as recent or newer |
Superseded: nothing is written |
Resolved |
|
One or more shared fields in the payload changed after the failure |
Needs Review: nothing is written, and the changed fields are listed in Fields Skipped |
Back to Pending Review |
|
Every field in the payload changed after the failure |
Superseded: nothing is written |
Resolved |
|
The payload can't be matched to exactly one record, other entries for the same record are open, or the write fails |
Replay Failed |
Back to Pending Review |
A superseded payload is closed rather than left open, because there's nothing left for anyone to do with it: the record already holds newer data. The dead letter queue keeps the payload and the reason, so it can still be inspected later.
The first check is all or nothing, on the assumption that each write from the sender carries the current value of every field it includes. If the sender only sends the fields that changed, a newer change to one field says nothing about the others. Most senders don’t send a timestamp per field, so in that case a newer Source Updated At should send the entry to review rather than close it as Superseded.
The Fields to Add
Principle 2 already sets out the dead letter queue's core fields: DLQ Record ID, Source System, Target Table, Raw Payload, Error Detail, Status, and Assigned Owner, with Status covering Pending Review, Replaying, Resolved, and Ignored. The integration fills three more when it writes an entry:
- Target ID (single line text): the sender's ID for the record the payload updates; here, the order ID.
- Source Updated At (number): the sender's timestamp from the payload, used to sort a batch.
- First Attempt At (date and time): when the integration first tried the write, in UTC.
The replay uses the rest:
- Replay Requested (checkbox): checked by the Replay button, cleared by the replay script.
- Replay Requested By (last modified by, scoped to Replay Requested): who pressed the button, until the script clears the checkbox.
- Replay Outcome (single select): Replayed, Partially Replayed, Superseded, Replay Failed.
- Fields Replayed, Fields Skipped, Values Before and Replay Notes (long text), and Replayed At (date and time).
On the target table, Orders here, add Source Updated At (Timestamp) if the live integration doesn't already maintain it, and have the live integration write the sender's timestamp to it on every successful write, since without that the first check has nothing to compare against. Then add a Last modified time field for each field with more than one writer, scoped to that field.
The Replay button on the triage interface is an Update record button that checks Replay Requested. The automation below runs when that box becomes checked.
The Replay Script
The script writes directly to Orders, so any validation the live pipeline applies beyond Airtable's own field types has to run here too. Keep those rules in one place that both use, or have the replay hand the payload back to the pipeline and record the result.
It also saves Values Before on the dead letter queue entry before it writes to Orders, so if the run fails between the two writes, the entry still holds what the order contained beforehand. On an entry marked Replay Failed, Values Before therefore shows what the order held before the attempt, and the order itself needs checking to see whether the write landed.
Pressing Replay Twice
Three things make a second write from the same entry very unlikely.
- The trigger. The automation starts when Replay Requested changes from unchecked to checked. Pressing the button again while the box is still checked doesn't change it, so it doesn't start a second run.
- The status check. The script's first write sets Status to Replaying, and any run that finds Status other than Pending Review exits without writing. Reading the status and setting it are two separate steps, so two runs started at the same instant could still both pass. Both would write the same payload, so the order would end up the same either way.
- The timestamp. A replay that writes also sets the order's Source Updated At to the payload's timestamp. If the same payload were replayed again later, the first check would find a timestamp at least as recent and close it as Superseded.
If a run fails before it can record anything, the entry stays at Replaying with Replay Requested still checked, and pressing Replay won't start a new run. Add a view of entries that have been at Replaying for more than a few minutes, so the integration owner can see them, and reset each one by setting Status back to Pending Review and clearing Replay Requested.
Replaying a Batch
After an incident, a dozen entries may be waiting at once, and two kinds of order matter.
Records that others depend on go first. In the pillar's example, an order fails because its account doesn't exist yet. If that account's own create is sitting in the dead letter queue too, replaying the order first fails again. Replay targets in dependency order: accounts before orders and orders before order lines.
Several entries for the same record are replayed as one write. If O-1 has three failed updates, replaying them one at a time doesn't work with the second check: the first replay's own write updates the Last modified time fields, and the next entry would then skip those fields as if someone else had changed them. That's why the script above refuses to replay an entry while another entry for the same record is still open. Handle them together instead:
- Close every entry whose Source Updated At is the same as or older than the record's as Superseded.
- Merge the rest from oldest to newest, so each newer payload overrides the fields it carries, and the result holds the latest value of every field.
- Run the second check once, against the oldest remaining entry's First Attempt At, write once, and set the record's Source Updated At to the newest entry's timestamp. Comparing against the oldest entry is conservative: an edit made between two failures is skipped even if a newer payload came after it, and the reviewer sees it in Fields Skipped.
- Close each entry with the fields of its own that made it into the write.
Checking Replay Requested on twelve entries at once starts twelve separate runs, with nothing deciding the order they finish in, so a batch needs a single script that sorts the entries by dependency and then by Source Updated At and works through them in that order. If it runs as an automation, it has the same time limit as the replay script, so split a large batch across several runs.
What the Audit Trail Shows
Every closed entry answers four questions without anyone opening a log. Who asked for the replay is in Replayed By, and when it ran is in Replayed At. What it changed is in Fields Replayed, together with Values Before, which holds what those fields contained before the replay overwrote them, as text. What it deliberately didn't write is in Fields Skipped, with the reason. If a replay turns out to have been wrong, Values Before is what you restore from.
Testing It in a Sandbox
Run each case against a sandbox copy of the base, with a dead letter queue entry built from a real payload:
- A clean replay: an entry whose order hasn't changed since. It should close as Replayed, with Values Before holding the old values.
- A newer change from the sender: send a newer update for the same order through the live integration, then replay the older entry. It should close as Superseded, and the order should keep the newer value.
- A shared field edited after the failure: change Delivery Date by hand, then replay. It should close as Partially Replayed, with Delivery Date in Fields Skipped and the hand edit intact.
- A second press: press Replay on an entry that's already closed. Nothing on the order should change.
- A missing order: replay an entry whose order ID matches nothing. It should return to Pending Review as Replay Failed, with the reason in Replay Notes.
- Two open entries for one order: press Replay on one of them. It should return as Replay Failed, asking for a batch. Then run the batch script and check that the order ends with the newest value of each field.
- A dependency: queue an account create and an order update that depends on it, and run the batch script. The account should be written first.
If you have a dead letter queue nobody wants to replay because nobody's sure what it will overwrite, Schedule a Discovery Call with InAir and we'll build the checks with you.